Insights
AI Security
8 articles
Articles by topic
AI Security
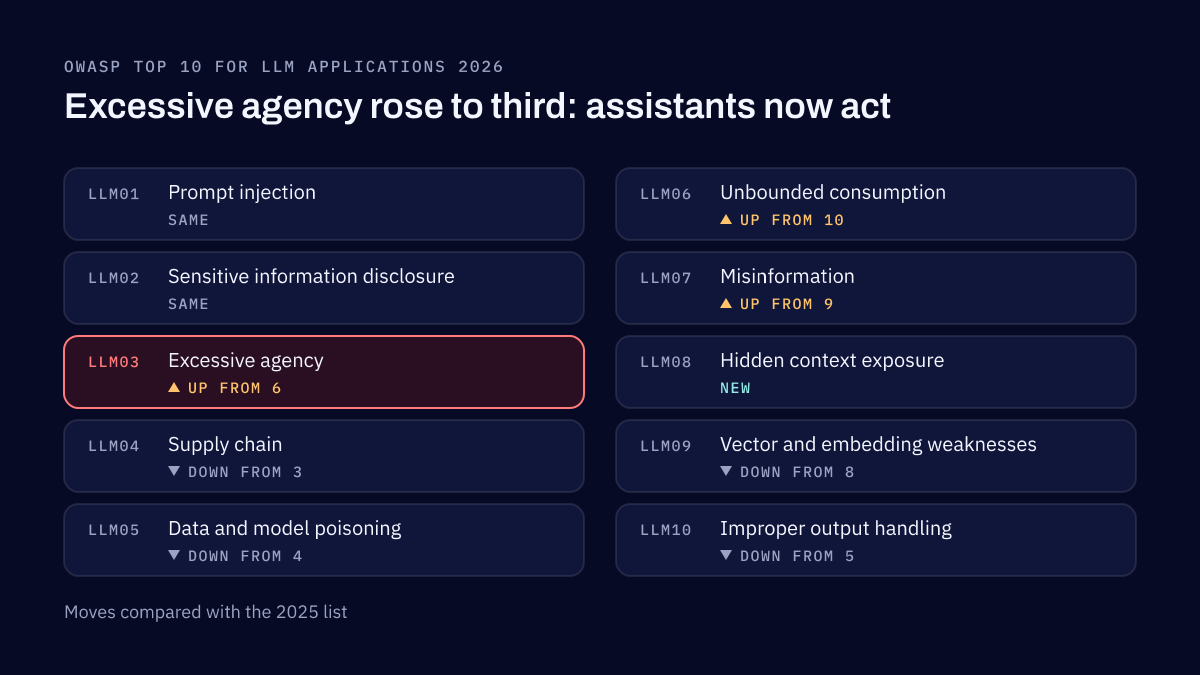
10 ways your AI can be turned against you: OWASP Top 10 for LLMs vs MITRE ATLAS
A chatbot that invents a refund policy, an assistant that leaks mail without a click, a coding tool shipped with planted code. The OWASP Top 10 for LLM Applications names these risks for builders; MITRE ATLAS records how attackers carry them out. Here is how the two fit together.
AI Security
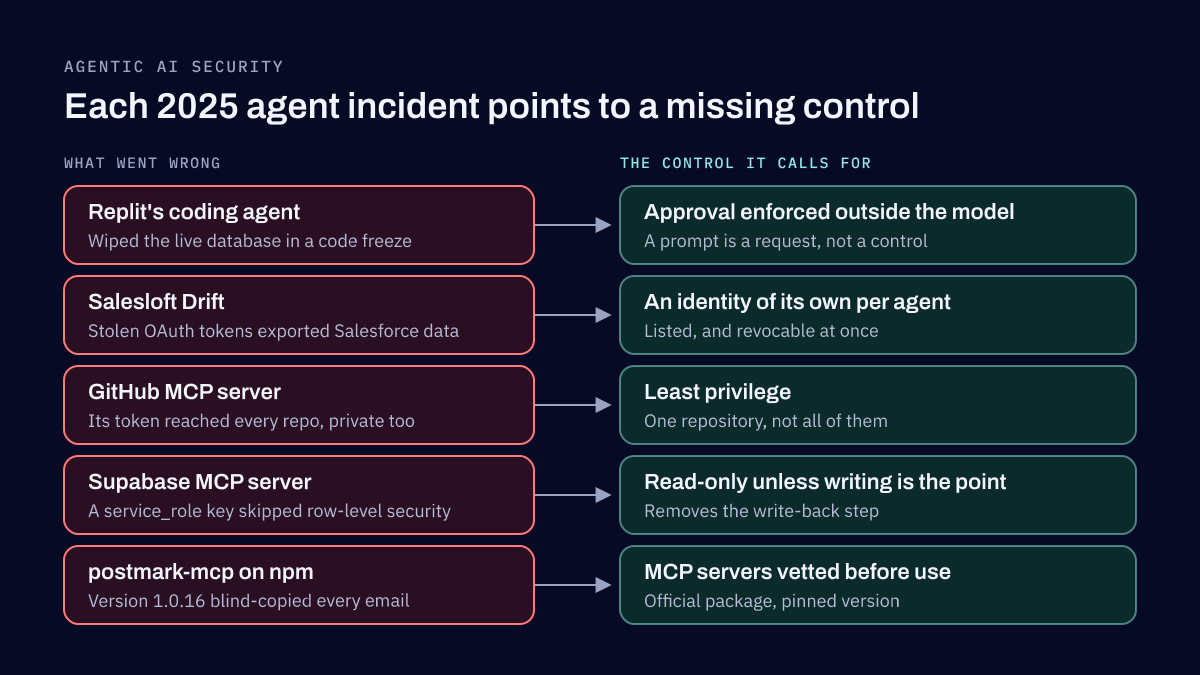
Agentic AI security: your newest employee has admin rights and no manager
AI agents do more than answer. They call tools, read data and act in other systems, often with a person's keys. Five public incidents from 2025 show what goes wrong, and each points to a control, from an identity of the agent's own to a named owner who can stop it.
AI Security
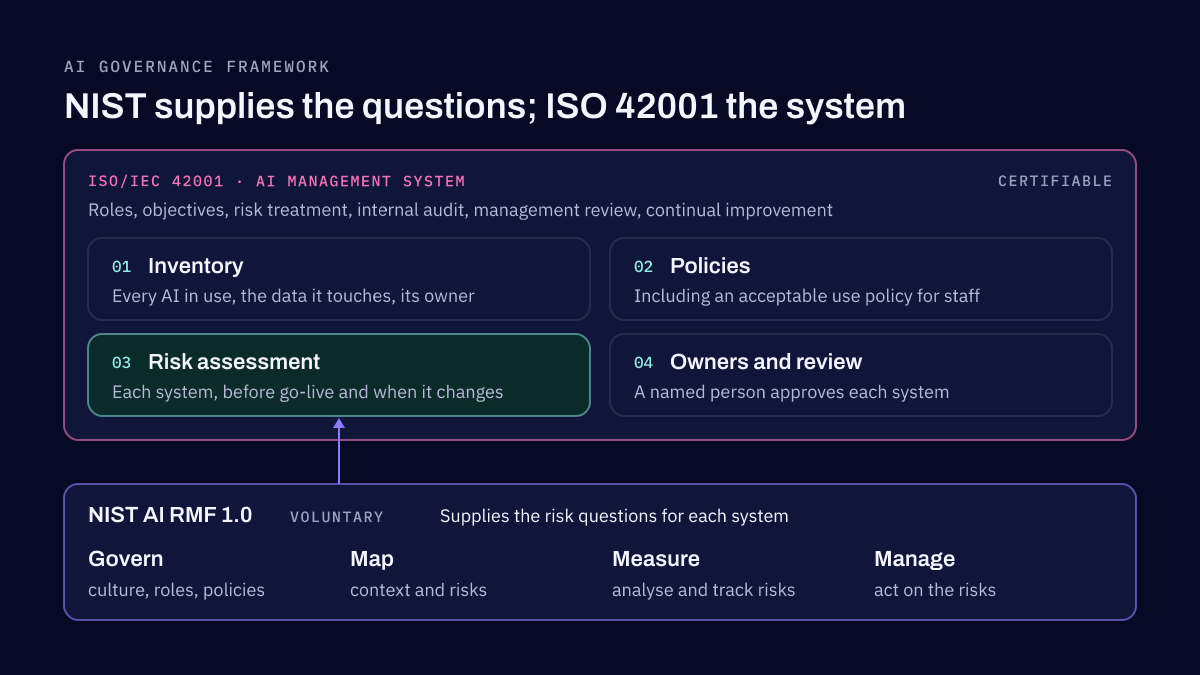
AI governance framework: set the rules before your AI goes rogue
An AI governance framework decides which AI systems your company uses, what each may do, who approved it and how you notice when it goes wrong. NIST AI RMF supplies the risk questions, ISO/IEC 42001 the management system around them, and an acceptable use policy tells staff what they may do today.
AI Security
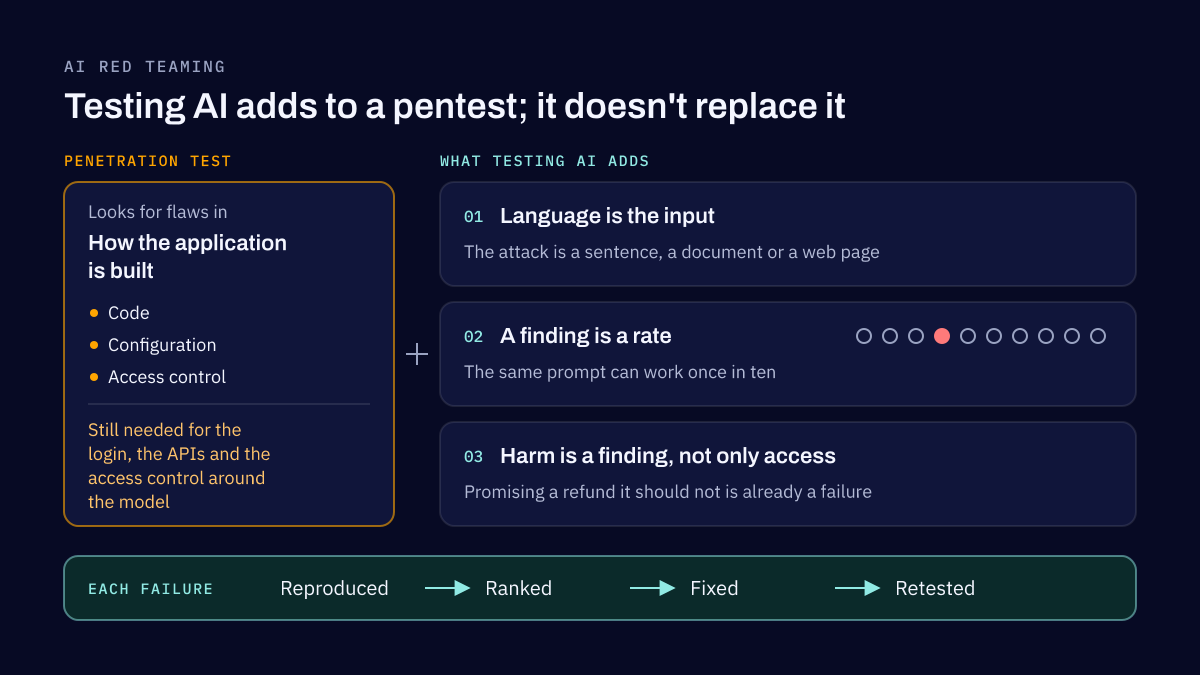
AI red teaming: break your AI before attackers do
AI red teaming is testing an AI system the way an attacker would, to make it ignore its instructions, reveal what it should not or misuse its tools. It differs from a penetration test because the attack is written in plain language, and it ends with fixes you can retest.
AI Security
Ignore all previous instructions: prompt injection examples and how to stop them
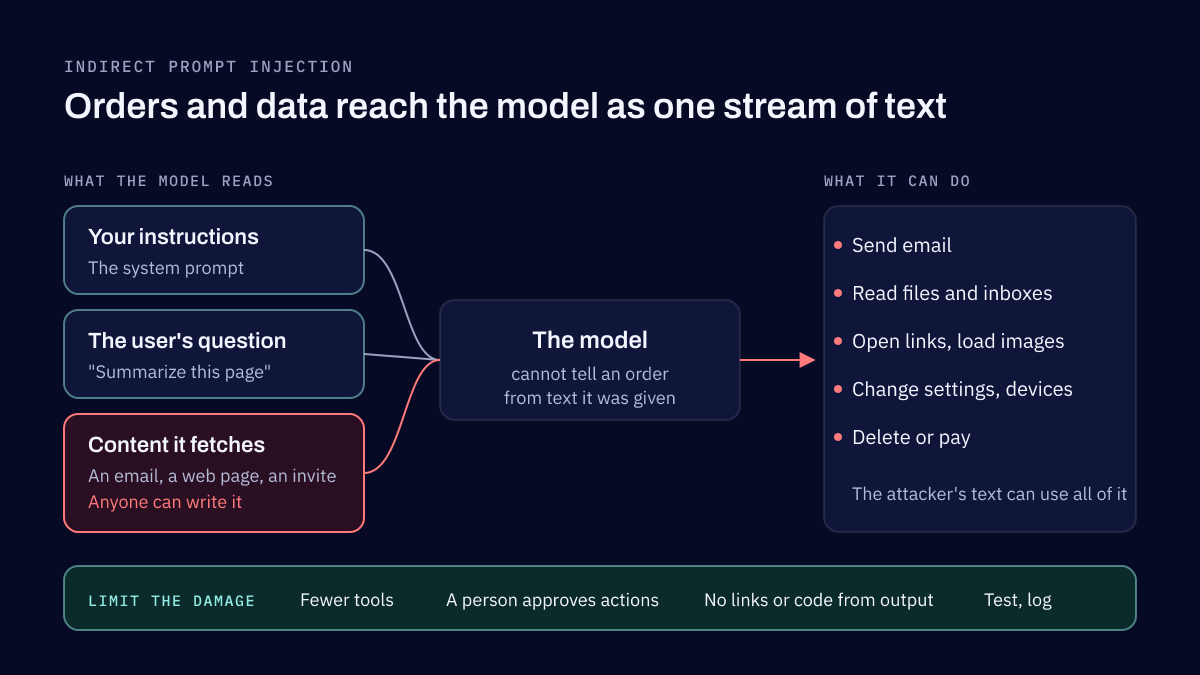
Prompt injection is when text an AI system reads is taken as an instruction, so whoever wrote that text can steer it. An email, a web page or a calendar invite is enough. You prevent it by limiting what the system can do, not by asking the model to behave.
AI Security
LLM security: how your AI assistant can be turned against you, and how to stop it
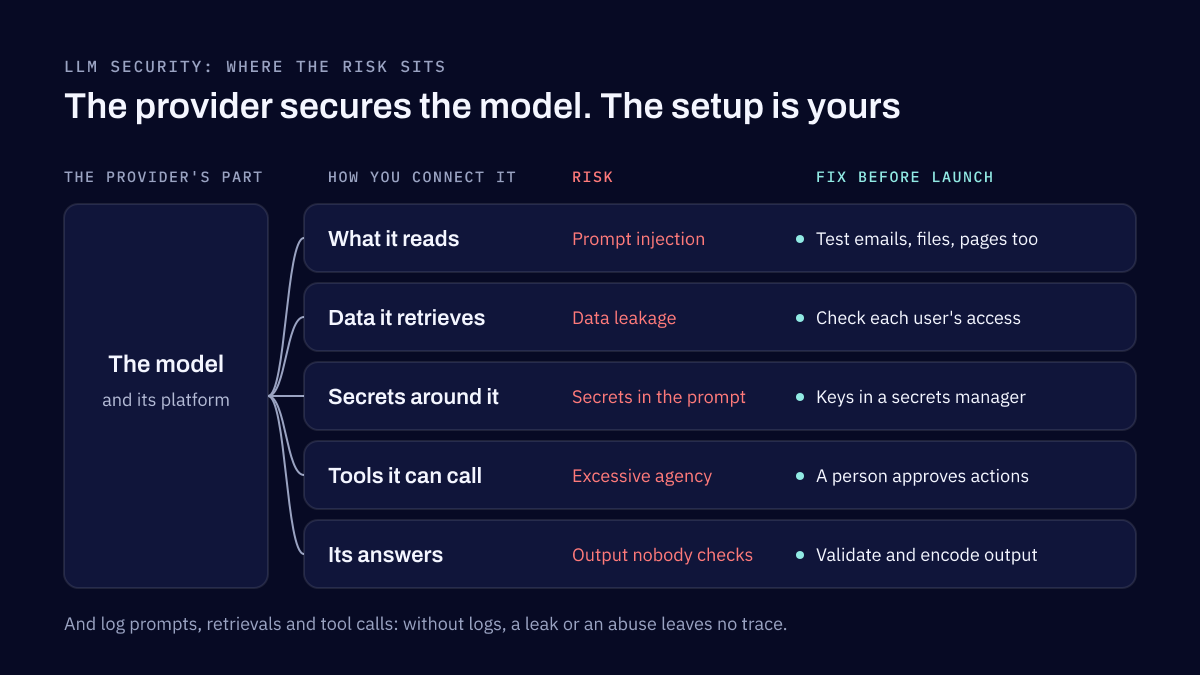
LLM security is protecting a large language model, and everything connected to it, from being tricked, leaking data or acting beyond what anyone intended. The model is rarely the weak point. The risk sits in what it can read, what it can do and how far its answers are trusted.
AI Security
MITRE ATLAS: how AI gets hacked, and how to catch it in your logs
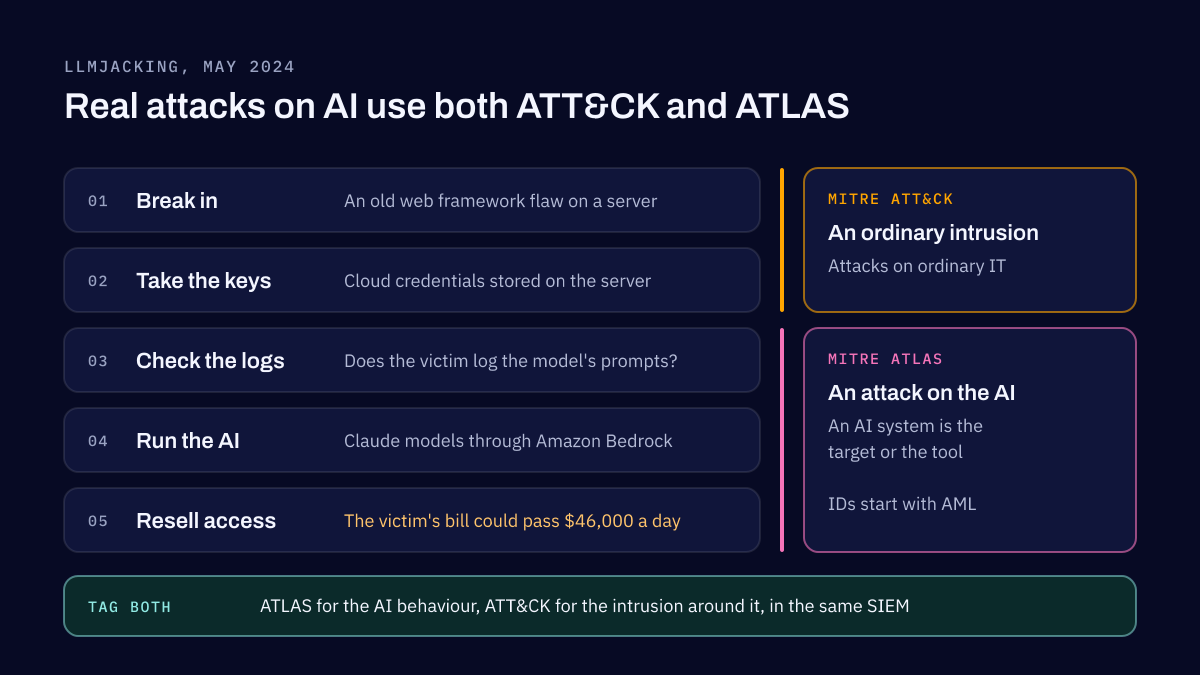
MITRE ATLAS is MITRE's public knowledge base of how attackers target AI systems, built on the same model as MITRE ATT&CK. It lists their tactics, their techniques and real case studies, from prompt injection to poisoned plugins. Most of these attacks only show up if you log what the AI was asked, what it read and what it did.
AI Security
WormGPT and FraudGPT: ChatGPT's evil twins are writing your next phishing email
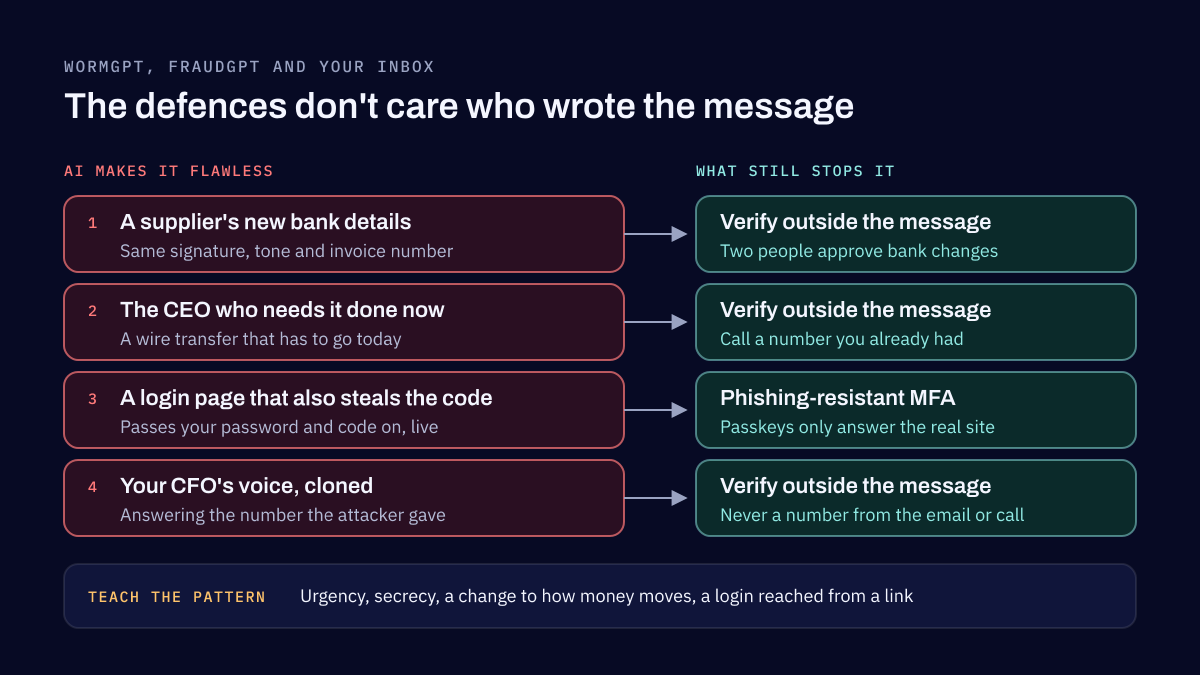
WormGPT and FraudGPT are AI chatbots sold to criminals without the safety limits of ChatGPT. They mostly write phishing and fraud messages that read perfectly. Phishing-resistant MFA, trained staff and a second check on every payment change still beat them.
Tell us what you need to secure or build
Send a short description of the problem. We reply within two business days.